AI Trainer & LLM Evaluator • Embedded Systems Engineer • Smart Metering Lead
Hi, I'm Alfi. For over ten years, I've designed custom PCBs, microcontroller firmware, and industrial metering solutions for teams in automotive, energy, and public utilities. Since 2021, I've also worked with global AI teams to test large language models, rank competing responses side by side, and catch factual or cultural errors in Indonesian and English.
Building physical hardware teaches you to respect small details. When a board trace is noisy or a sensor reading drifts, something real stops working in the field. I bring that same practical habit to AI quality work: reading user prompts carefully, checking claims against real sources, and writing clear notes on why one answer works better than another.
PCB design, embedded C++, IoT hardware, and technical sales
AI annotation & search evaluation tasks across 100+ task types
Average QA score on Indonesian LLM evaluations (2026)
Sales growth contribution in smart kWh & water metering
Core Capabilities
My day-to-day background combines circuit design on the bench, field coordination with utility customers, and structured evaluation of language and image models.
I test how models handle real user requests, multi-turn memory, grounded facts, and Indonesian local nuance. Instead of vague feedback, I write concrete, turn-by-turn rationales explaining what went wrong and how to fix it.
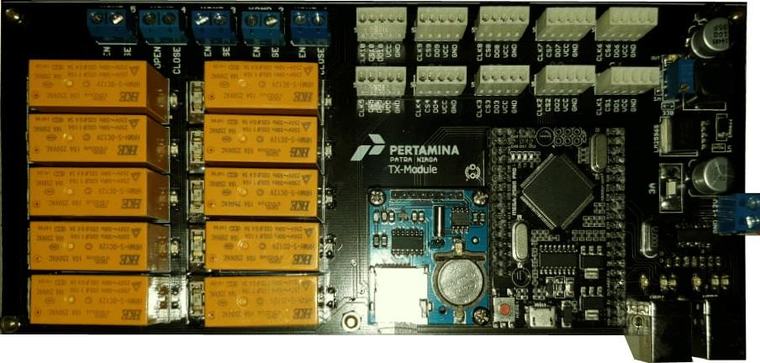
From schematic capture to SMD board assembly and C++ firmware, I build reliable controllers that read industrial sensors, drive high-current motors and pneumatic valves, and talk to Android tablets or local Wi-Fi web servers.
I work directly between utility clients like PLN, government certification bodies, and internal R&D engineers. That includes preparing tender proposals, running field training, and resolving technical issues on smart kWh and water meters.
Selected Portfolio
Click any card below to inspect actual hardware photos, circuit architecture, and project context.
Showing 6 projects
AI Quality & RLHF
Good AI evaluation requires more than picking which paragraph looks nicer. Models often write confident answers that miss a time constraint, invent a detail, or sound unnatural to a native Indonesian reader.
Since 2021, I have worked across OneForma/UHRS, Outlier, and Meridial Marketplace (by Invisible) on evaluation workflows that test factual grounding, multi-turn personalization, and visual prompt alignment.
Languages Rated
Review Indonesian model outputs for local user intent, tone, response length, and automated-judge accuracy across four workstreams, maintaining an average QA score above 4.75 out of 5.00.
Tested long multi-turn conversations for user preference retention and contextual reasoning, logging exact turn-level evidence whenever a model dropped prior context or misread dates.
Designed challenging test prompts, verified source groundedness and instruction compliance, ranked competing model outputs side by side, and rewrote flawed responses.
Assessed hundreds of AI-generated images against dual reference photos for visual artifacts and prompt fidelity (QA >4.5/5), building on 10,000+ search relevance tasks at OneForma/UHRS.
Hardware & Field Footage
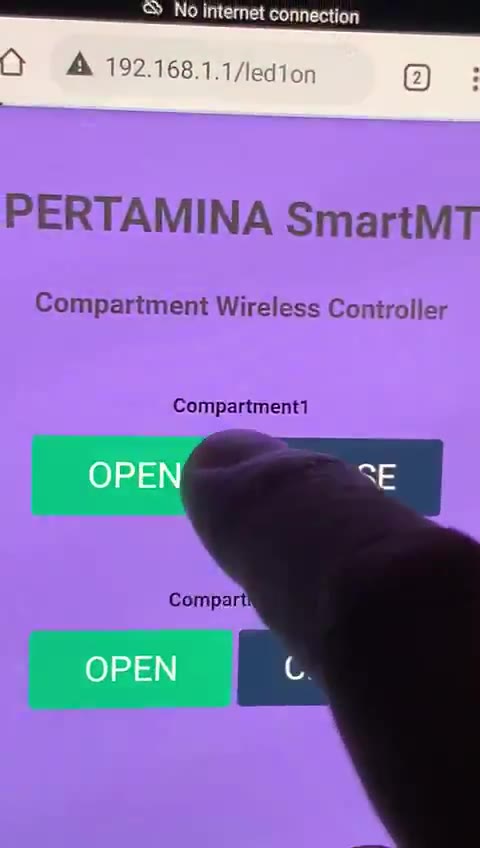
Short bench and in-vehicle clips showing physical boards, motor drivers, touchscreen interfaces, and wireless control workflows in operation.
Career History
Associate of Science in Telecommunications Engineering
Direct Contact
Whether you need an Indonesian/English AI quality evaluator, custom microcontroller and PCB development, or technical leadership on smart metering solutions, feel free to reach out directly.